One GPU in a box. Then eight.
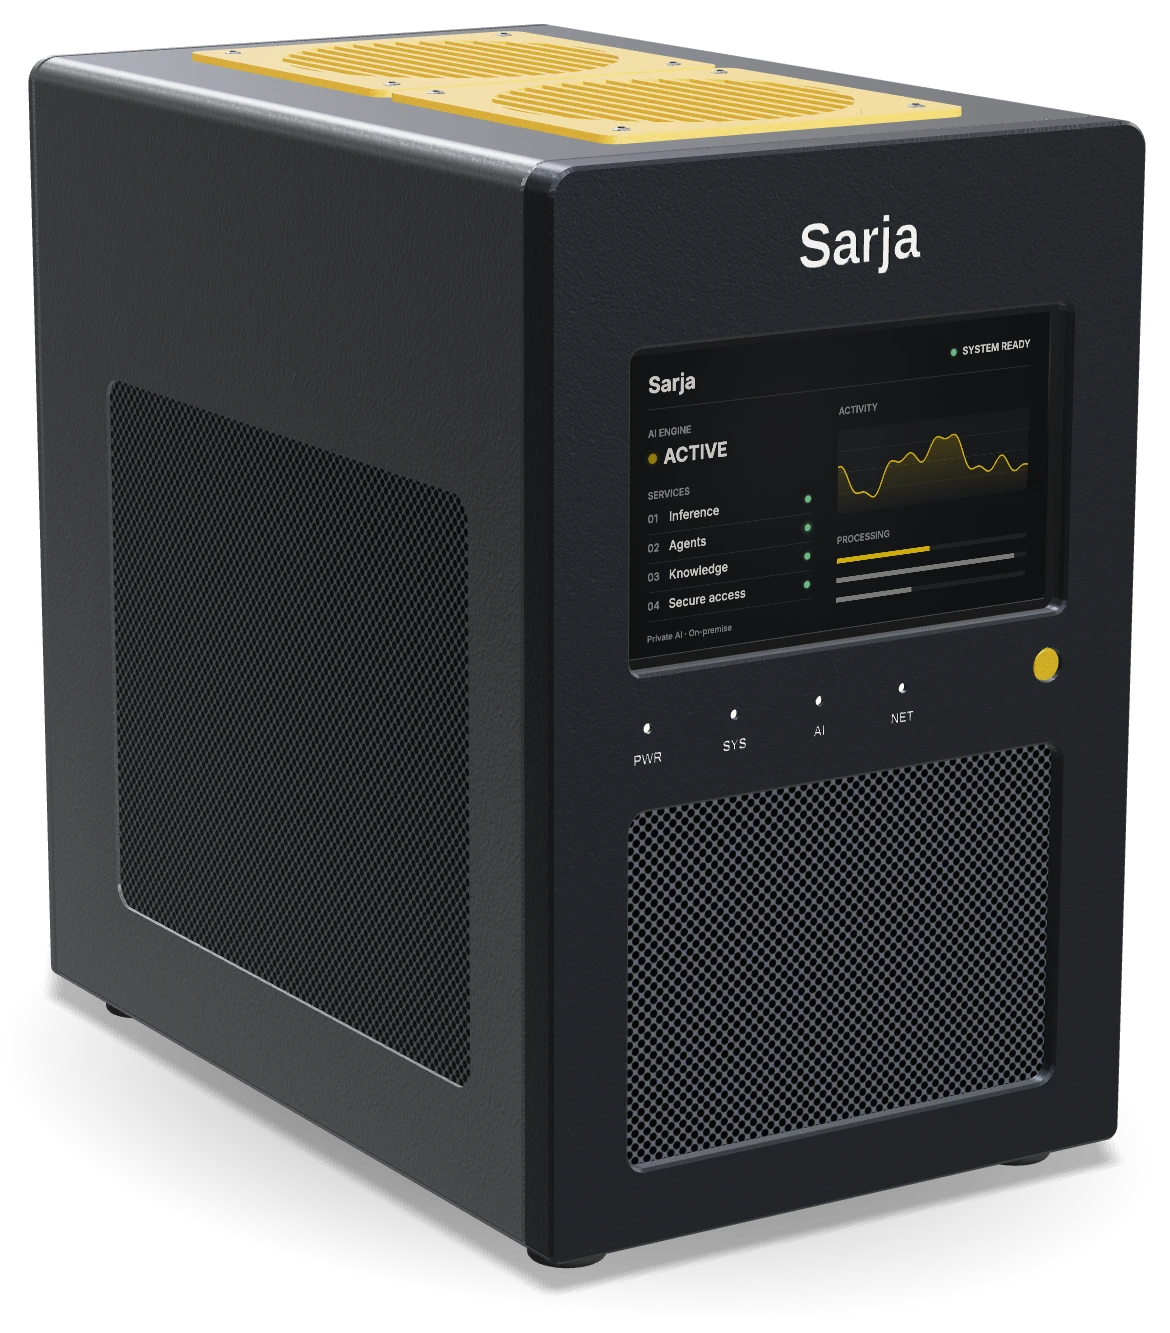
SarjaBox Mini1 GPU · air-cooled
Previous generation
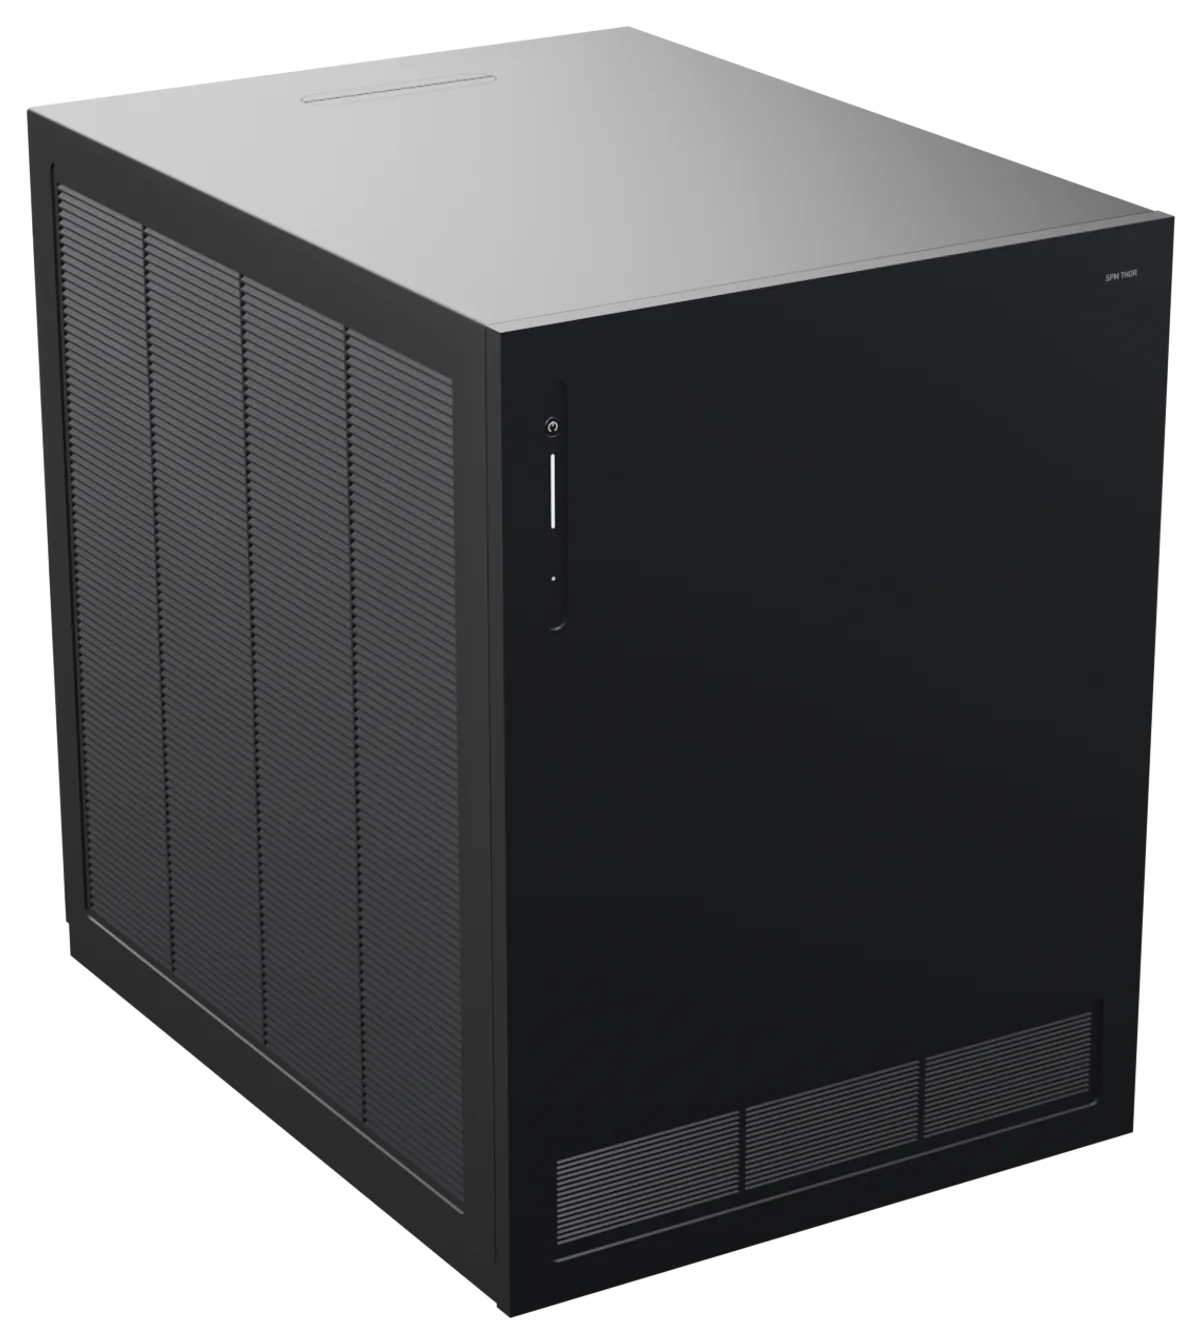
SPM ThorUp to 8 GPUs · liquid-cooled
Flagship concept
SarjaBox Mini was the single-GPU generation. What it was
Take it apart.
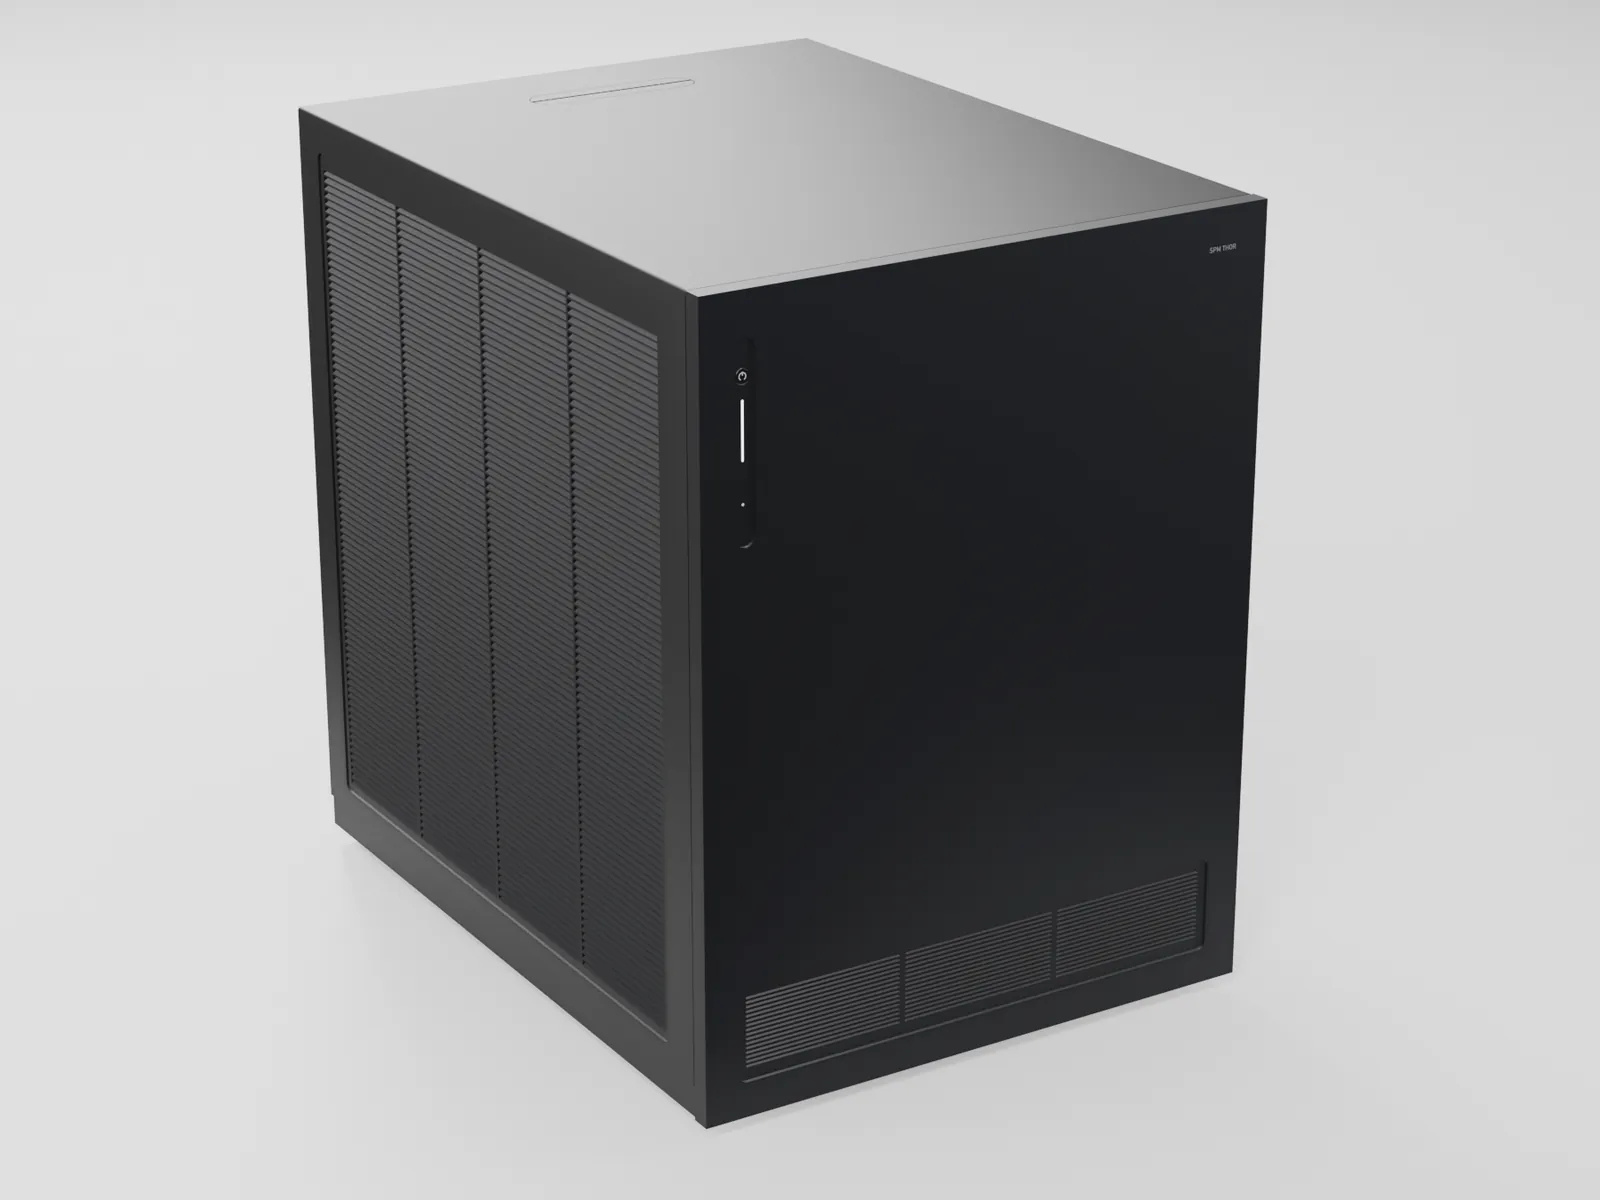
Front three-quarter
A 22.3-litre machined aluminium cube. The top shell is one U-shaped part with integrated louvre cassettes; the front carries only the control strip and a low intake band.
How eight GPUs share 22 litres.
No per-GPU cables and no hoses to undo. Every blade plugs into one backplane for data and power, and one liquid loop for cooling.
From one processor to eight blades over PCIe Gen5.
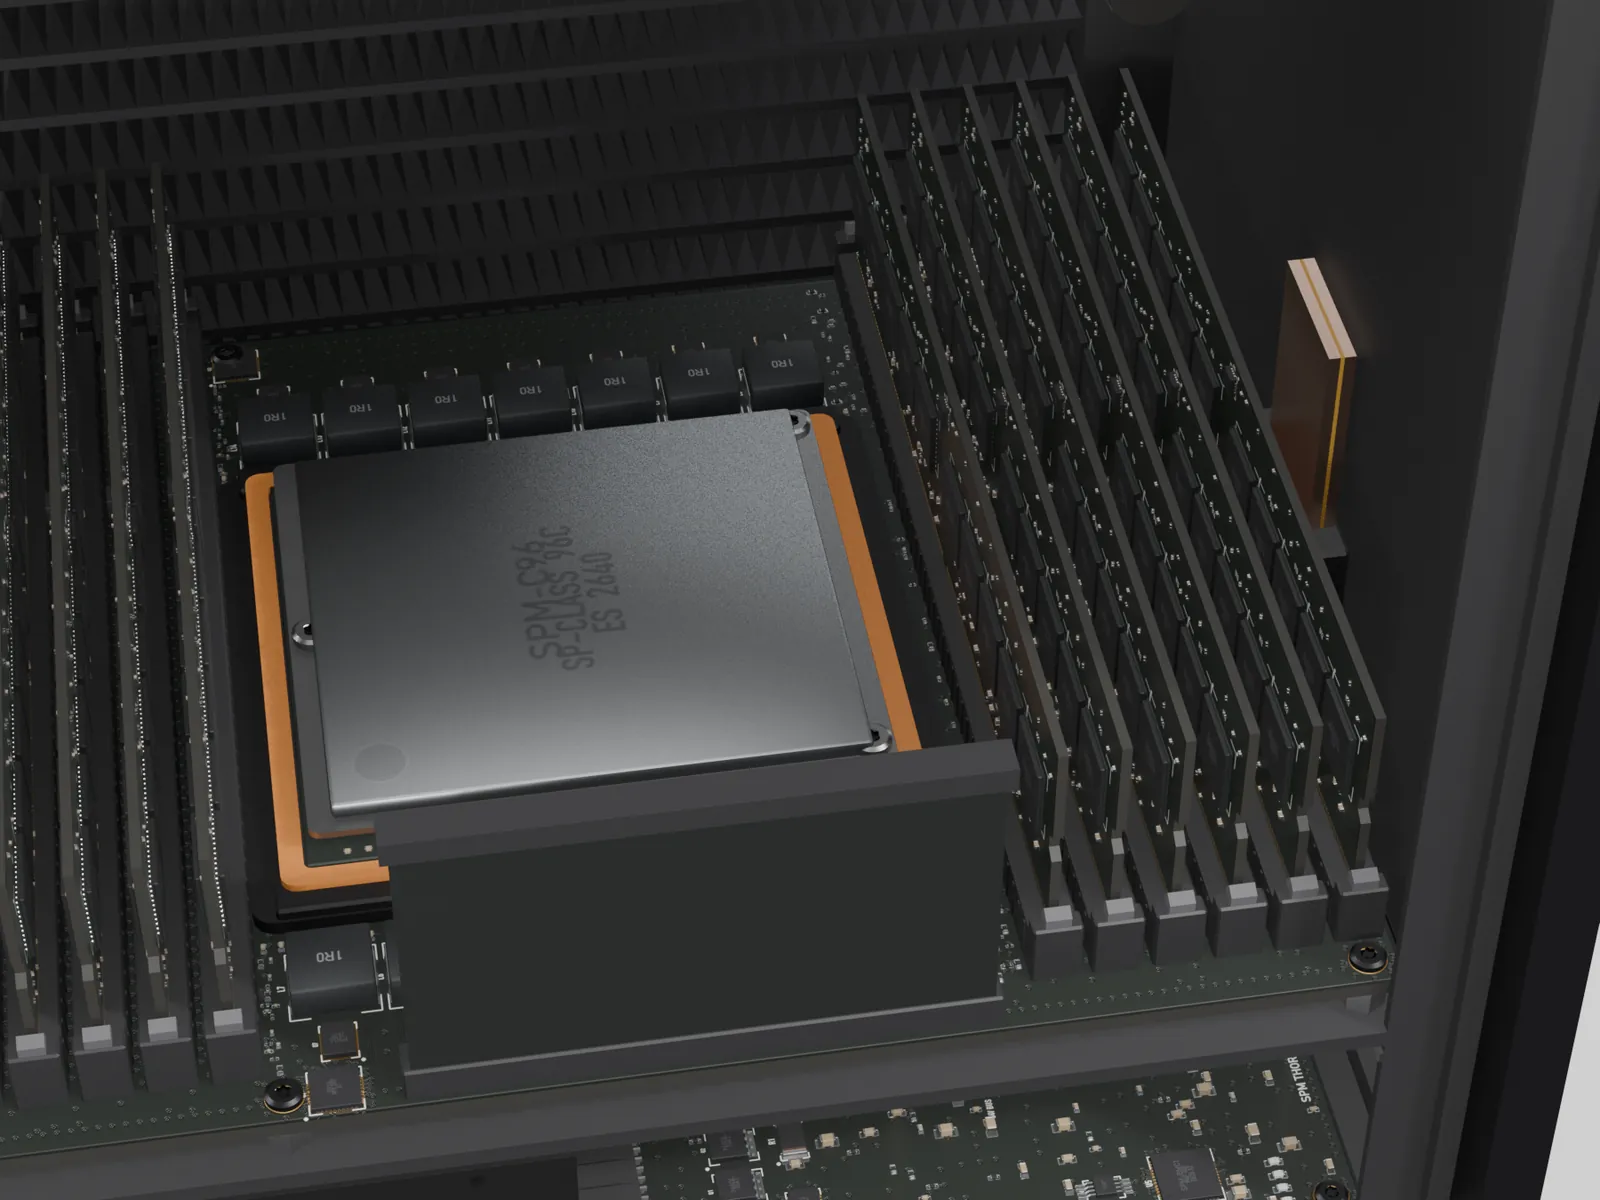
Concept- 1SP5-class CPUSingle server socket with twelve DDR5 channels
- 2Riser spine×128 PCIe Gen5 link to the backplane, with retimers
- 3BackplaneEight slot receptacles with retimers and per-slot eFuses
- 48 × GPU bladePCIe Gen5 ×16 each, through a blind-mate edge connector
Two GPUs to eight.
Start with what the work needs. Add blades to the empty slots later — same machine.
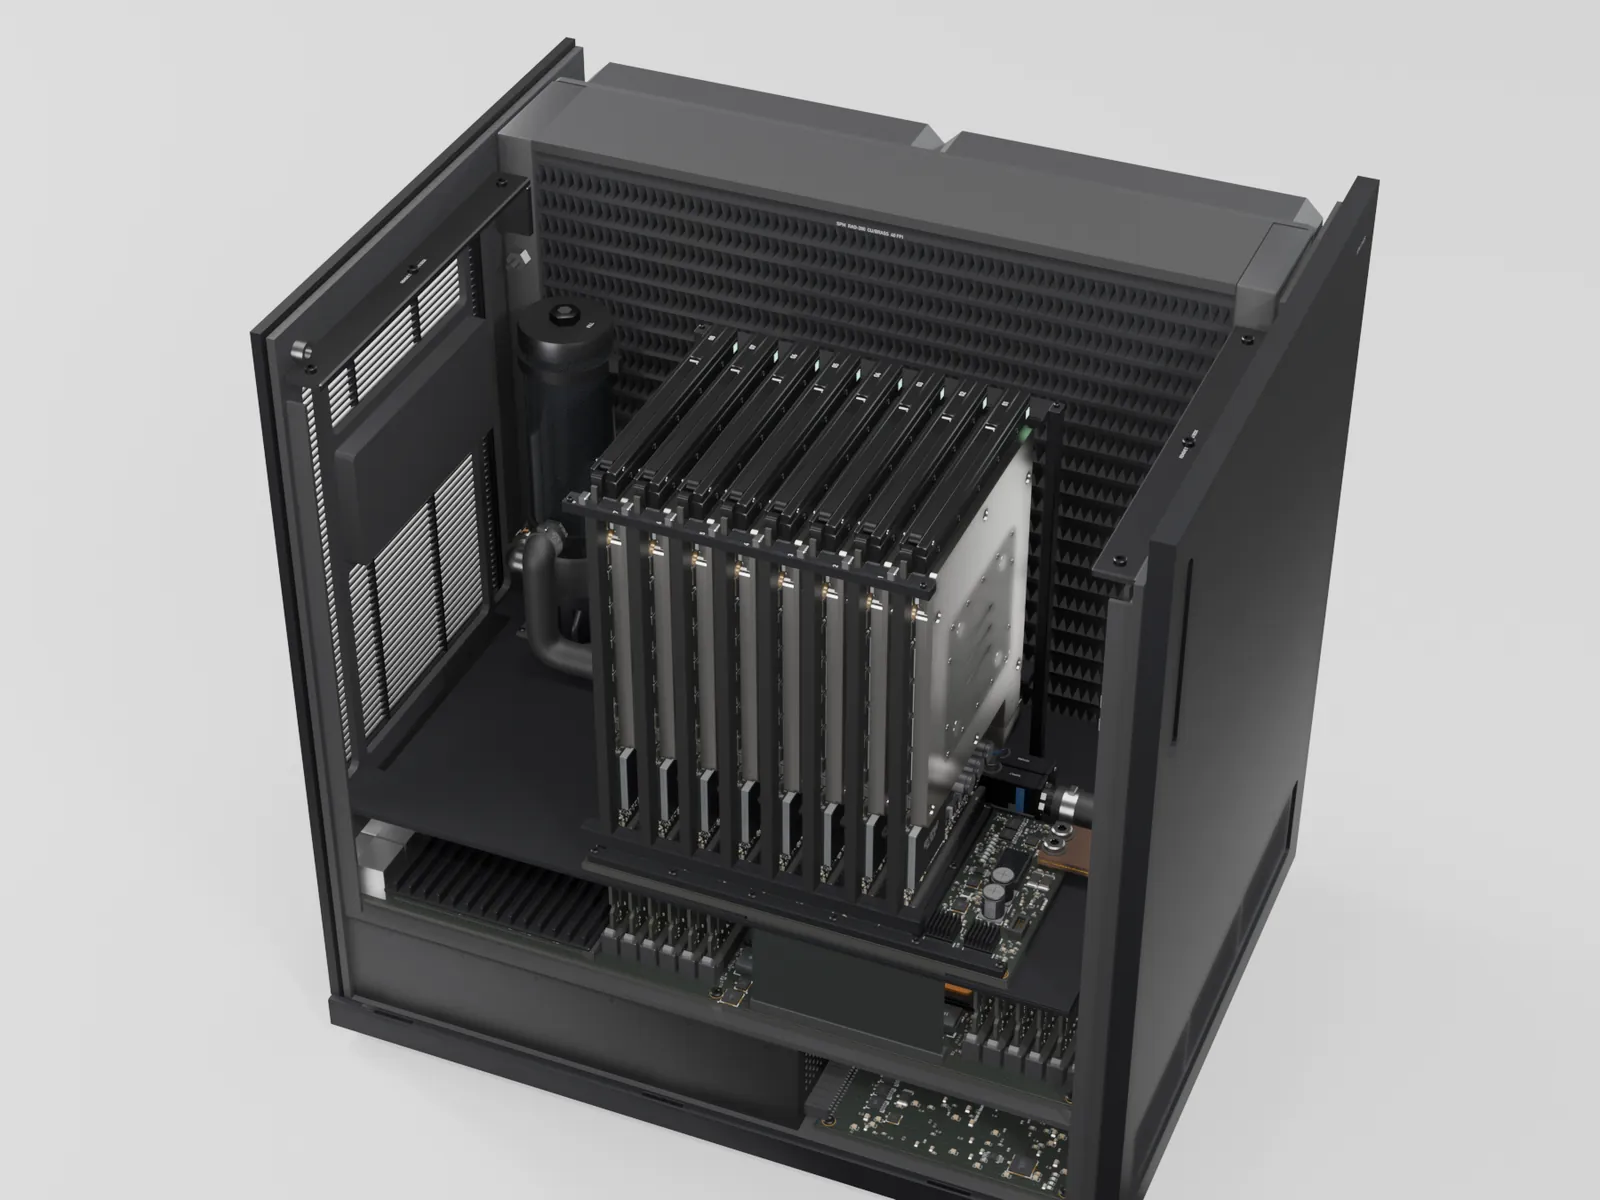 Cut-away · concept render
8 of 8 slots
8 GPUs
- GPU memory Concept
- 8 × 48 GB — 384 GB in total, as 8 separate memories
- At full load Estimate
- About 3.0 kW DC, on a 200–240 V / 16 A circuit
Each GPU has its own memory. Eight 48 GB GPUs are 384 GB in total, but no single process sees 384 GB: a model split across them gets each GPU's share, minus what parallelism duplicates.
Empty slots carry keyed blanking covers, ready for more blades. Memory as the blade is modelled (16 × 3 GB GDDR7 per GPU); a 96 GB clamshell blade is a concept variant.
What would it take?
Memory estimates at 48 GB per GPU, as modelled — not benchmarks.
- A private assistant for a teamA 32B model at FP8, eight people at once, 16k tokens each2 GPUsAbout 52 GB
- A 70B-class modelAt FP8, four sessions of 16k tokens4 GPUsFits on 2, tightly
- A 235B mixture-of-experts modelAt 4-bit, four sessions of 16k tokens8 GPUsFits on 4, tightly
- The largest open modelsA 480B model at 4-bit, one sessionAll 8 GPUsA tight fit
- Many people, one smaller modelA 14B model at FP8, a copy on every GPU8 copiesAbout 17 GB each
- Image and video generationOne GPU per generation in flight1 GPU eachUp to eight at once
What's real, and what isn't yet.
- Verified in model
Verified in the model
- Every part fits: no interferences with eight GPUs installed
- Blade, shell, rear-panel, core and GPU-deck service paths are clear
- The 235 × 309 × 306.5 mm, 22.3-litre envelope
- Estimate
Estimates
- About 300 W per GPU and about 3 kW at full load
- Coolant temperatures and flow
- A 200–240 V / 16 A circuit at eight GPUs; server-class noise
- Concept
Concept
- The GPU blade, its memory — 48 GB as modelled, 96 GB as a clamshell variant — and the backplane
- The system board and its SP5-class processor
- GPUs linked over PCIe Gen5, with no dedicated GPU-to-GPU link
- Not yet
Not yet
- Measured performance: nothing is benchmarked
- The radiator-cassette and power-module slide-outs
- A price or an availability date
The full specification — every figure tagged
Enclosure
- Envelope
- 235 W × 309 D × 306.5 H mm (313.5 mm on its feet)Verified in model
- Volume
- 22.3 litresVerified in model
- Construction
- Outer enclosure carrying no hardware; every component on a slide-out coreDesign intent
- Finish
- Black anodised aluminium shell and fascia; powder-coated steel coreDesign intent
GPU system
- GPU positions
- 8 vertical blades on a 15 mm pitchVerified in model
- Populations
- 2, 4, 6 or 8 GPUs on one platform; empty slots carry keyed blanking coversDesign intent
- GPU blade
- Custom bare-board blade for an RTX PRO-class GPU on a nickel micro-channel cold plate — not a retail cardConcept
- Power per GPU
- About 300 W — the radiator's limit per bladeEstimate
- GPU memory
- 16 GDDR7 packages on a 512-bit bus: 48 GB with 3 GB packages as modelled; a 96 GB clamshell variant fits the envelopeConcept
- Interconnect
- PCIe Gen5 ×16 per blade through backplane retimers and a riser spine to the CPU; no separate GPU-to-GPU linkConcept
Compute and I/O
- Processor
- SP5-class server socketConcept
- System memory
- 12 × DDR5 RDIMM, one per channelConcept
- Storage
- 4 × M.2 NVMe under a shared heatsinkConcept
- Networking
- 2 × QSFP112, 2 × 10G and a management RJ45Concept
- Other I/O
- USB-C, USB-A, mini-DP; baseboard management controllerConcept
Cooling
- Loop
- One loop: pump and reservoir, radiator, supply and return manifolds, self-sealing blind-mate couplings to every bladeDesign intent
- Radiator
- 286 × 288 × 45 mm crossflow core with 4 × 140 mm fans, behind louvres with no line of sight to the fansDesign intent
- Coolant
- About 44 °C supply and 52 °C return at 25 °C ambient, 5 L/minEstimate
- Leak handling
- Drip tray with a leak-sense strip under the manifoldsDesign intent
- Acoustics
- Server-class at full loadEstimate
Power
- Supplies
- 2 × 3.2 kW CRPS-format 54 V modules, 1+1, hot-swappable from the rearDesign intent
- Distribution
- Power distribution board and laminated copper busbars — no per-GPU cablesDesign intent
- System load
- About 3.0 kW DC with eight blades at about 300 WEstimate
- Mains
- A 200–240 V / 16 A circuit for the 8-GPU configurationEstimate
Service
- Top shell
- Press the flush handle, slide 10 mm back, lift offVerified in model
- GPU blades
- Raise the lever 75° and lift straight out — no tools, no coolant handlingVerified in model
- Core
- Rear panel off unlocks the core, which rolls out about 330 mm on roller carriagesVerified in model
- Compute access
- The GPU deck lifts 145 mm as one sub-assemblyVerified in model
- Checks
- No interferences assembled; blade, shell, rear-panel, core and deck paths and every mechanism arc clear. Radiator-cassette and power-module slide-outs are not yet verifiedVerified in model
Before you enquire
Can I buy one now?
Not yet. SPM Thor is in development and we're taking enquiries. There's no list price or availability date — an enquiry starts an engineering conversation about your workload and, as engineering progresses, a quote.
Which GPUs does it use?
Thor is designed around RTX PRO-class GPUs on custom liquid-cooled blades, each budgeted at about 300 W. The final GPU and blade are confirmed as engineering progresses, and any quote will say exactly what you get.
Where does it go, and how loud is it?
At six or eight GPUs it is estimated to draw about 2.4–3 kW and to be server-loud at full load, so it belongs in a comms or server room; eight GPUs are estimated to need a 200–240 V / 16 A circuit. We check your site before anything is quoted.
Why are there no performance figures?
Because nothing has been measured. Every number about models on this site is a memory estimate, labelled as one. Throughput will be published when it's measured on hardware.
NVIDIA, RTX and RTX PRO are trademarks of NVIDIA Corporation. SPM Thor is designed by SPM, a Sarja Technologies product brand, in partnership with Sarja AI.
Tell us what it has to run.
- 01Tell us the workloadThe models, the people using them, the data — or bring a configuration from this site.
- 02We size it with youGPUs and memory for the work, and the power, cooling and noise your site can take.
- 03A quote, as engineering allowsThere's no list price while Thor is in development; the quote says exactly what you get.